Multi-modal generative embedding model
Abstract
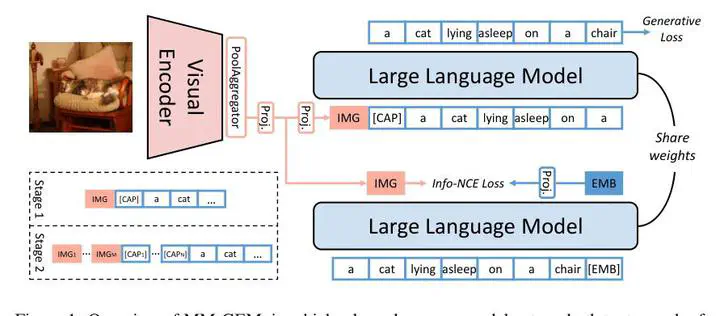
Most multi-modal tasks can be formulated into problems of either generation or embedding. Existing models usually tackle these two types of problems by decoupling language modules into a text decoder for generation, and a text encoder for embedding. To explore the minimalism of multi-modal paradigms, we attempt to achieve only one model per modality in this work. We propose a Multi-Modal Generative Embedding Model (MM-GEM), whereby the generative and embedding objectives are encapsulated in one Large Language Model. We also propose a PoolAggregator to boost efficiency and enable the ability of fine-grained embedding and generation. A surprising finding is that these two objectives do not significantly conflict with each other. For example, MM-GEM instantiated from ViT-Large and TinyLlama shows competitive performance on benchmarks for multimodal embedding models such as cross-modal retrieval and zero-shot classification, while has good ability of image captioning. Additionally, MM-GEM can seamlessly execute region-level image caption generation and retrieval tasks. Besides, the advanced text model in MM-GEM brings over 5% improvement in Recall@1 for long text and image retrieval.
本文提出多模态生成嵌入模型MM-GEM,将生成与嵌入两种目标统一于单个大语言模型中,实现每个模态仅需一个模型。通过引入PoolAggregator提升效率并支持细粒度嵌入与生成。实验表明,生成与嵌入目标并不显著冲突,模型在跨模态检索、零样本分类和图像描述等任务上表现优异,同时具备区域级描述生成与检索能力,并在长文本图像检索中取得显著提升。