ReactID: Synchronizing Realistic Actions and Identity in Personalized Video Generation
Abstract
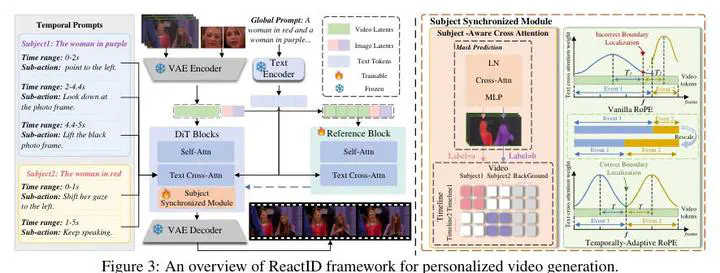
Personalized video generation faces a fundamental trade-off between identity consistency and action realism: overly rigid identity preservation often leads to unnatural motion, while emphasis on action dynamics can compromise subject fidelity. This tension stems from three interrelated challenges: imprecise subject-video alignment, unstable training due to varying sample difficulties, and inadequate modeling of fine-grained actions. To address this, we propose ReactID, a comprehensive framework that harmonizes identity accuracy and motion naturalness through coordinated advances in data, training, and action modeling. First, we construct ReactID-Data, a large-scale dataset annotated with a high-precision pipeline combining vision-based entity label extraction, MLLM-based subject detection, and post-verification to ensure reliable subject-video correspondence. Second, we analyze learning difficulty along dimensions such as subject size, appearance similarity, and sampling strategy, and devise a progressive training curriculum that evolves from easy to hard samples, ensuring stable convergence while avoiding identity overfitting and copy-paste artifacts. Third, ReactID introduces a novel timeline-based conditioning mechanism that supplements monolithic text prompts with structured multi-action sequences. Each sub-action is annotated with precise timestamps and descriptions, and integrated into the diffusion model via two novel components: subject-aware cross-attention module to bind sub-action to the specific subject of interest and temporally-adaptive RoPE to embed the rescaled temporal coordinates invariant to action duration …
本文提出ReactID框架,旨在协调个性化视频生成中身份一致性与动作真实性的矛盾。针对主体-视频对齐不精确、训练不稳定、细粒度动作建模不足三大挑战,从数据、训练和动作建模三方面协同改进:构建高精度标注的ReactID-Data数据集;设计由易到难的渐进式训练课程;提出基于时间线的条件机制,通过主体感知交叉注意力和时间自适应RoPE,将子动作与特定主体绑定并嵌入时间坐标,从而生成更自然、可控的视频。